Accessing historical 2016 data requires navigating specific archival repositories, understanding structured formats, and recognizing the technological standards of that era. Whether you are analyzing economic indicators, scientific research metrics, or public policy documents, retrieving reliable datasets from 2016 involves distinct verification steps, specialized database queries, and adherence to data preservation guidelines.
Introduction to 2016 Data Architecture
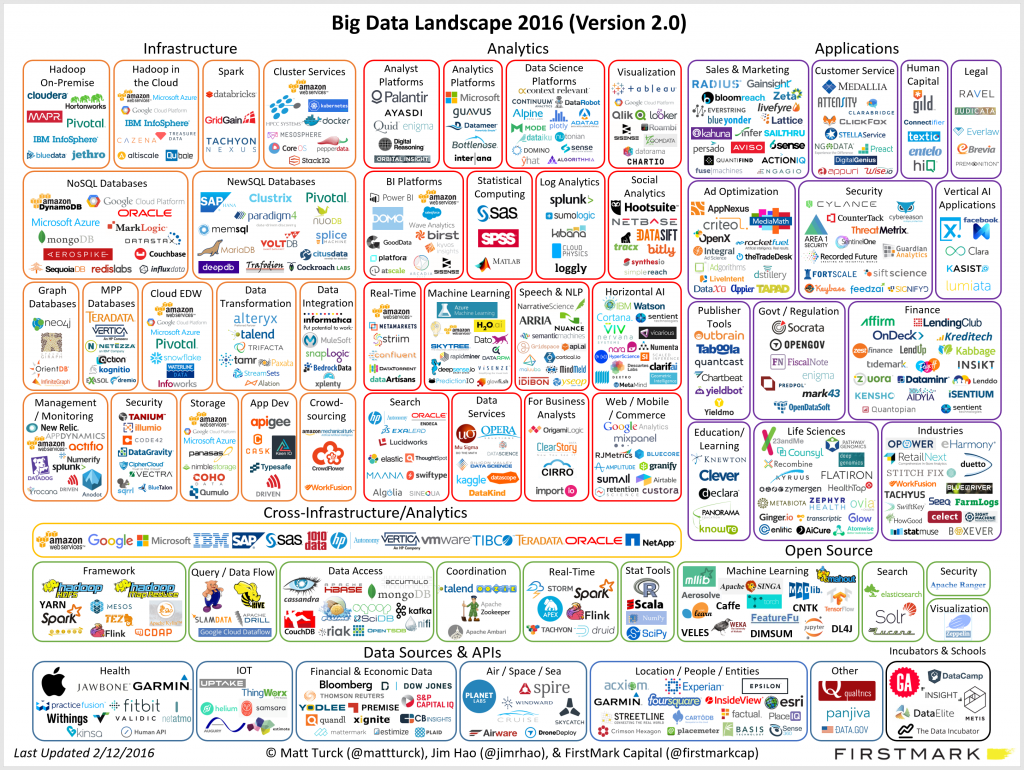
Data generated and archived in the year 2016 occupies a unique technological transition period. It sits squarely between the widespread adoption of cloud-native data lakes and the older, file-bound relational database management systems of the early 2010s. During this period, organizations increasingly relied on distributed storage frameworks like Apache Hadoop and early iterations of cloud object storage, while public agencies shifted toward open data portals.
For researchers, data analysts, and compliance officers, locating and utilizing 2016 data often means dealing with formats that may no longer be actively maintained on modern software stacks. Understanding how these datasets were originally structured—typically in CSV, JSON, legacy XML, or proprietary database backups—is essential for successful extraction and analysis today.
Key Categories of 2016 Data
When searching for information from this period, it helps to categorize datasets by their primary origin. Different sectors employed distinct collection methodologies and storage standards.
Economic and Financial Metrics
Financial data from 2016 reflects major global events, including shifting monetary policies, commodity price fluctuations, and significant geopolitical shifts. Central banks, international monetary funds, and national statistical offices published extensive transaction logs, macroeconomic indicators, and trade balances. These datasets are typically maintained in standardized repositories such as the World Bank Data catalog or the International Monetary Fund (IMF) archives.
Scientific and Environmental Records
Environmental monitoring data from 2016—including climate telemetry, satellite imagery, and ecological surveys—set crucial baselines for modern longitudinal studies. Agencies like NASA, the National Oceanic and Atmospheric Administration (NOAA), and the European Space Agency (ESA) provide access to raw telemetry and processed indices from this period through specialized scientific portals.
Public Sector and Government Portals
Government transparency initiatives in the mid-2010s led to a surge in open data portals at municipal, national, and international levels. Datasets from 2016 covering census information, public transit logs, and legislative voting records are frequently archived in static repositories or deep-storage buckets, requiring specialized index searches to retrieve.
Verification and Quality Assurance of Historical Datasets
Before integrating historical records into modern analytical pipelines, data integrity must be verified. Data degradation, missing metadata, and undocumented schema changes are common pitfalls when working with files from past decades.
Metadata Integrity
The utility of any dataset depends heavily on its accompanying metadata. For 2016 data, verify that the schema definitions, variable coding books, and unit measurements match documentation standards of that era. Ambiguities in time-zone stamps (such as handling daylight saving time transitions in log files) frequently require manual correction during data cleaning.
Checksums and Provenance
To ensure that retrieved files have not been corrupted during long-term storage migration, always check cryptographic hashes (such as MD5 or SHA-256) if provided by the repository. Establishing a clear chain of provenance protects analytical models from relying on corrupted or altered historical inputs.
Comparison of 2016 Data Repositories
The following table outlines the primary sources, typical file formats, and access methods for retrieving verified 2016 data across different sectors.
| Sector | Primary Repositories | Common Formats | Access Method |
|---|---|---|---|
| Macroeconomics | World Bank, IMF, OECD | CSV, XLSX, API endpoints | Direct download or programmatic API query |
| Environmental Science | NOAA, NASA Earth Data | NetCDF, HDF5, GeoTIFF | Specialized scientific servers, FTP, or cloud buckets |
| Government & Public Policy | Data.gov, Eurostat, Municipal Portals | CSV, JSON, XML | Open data portals and bulk archives |
| Academic Research | Zenodo, Dryad, Figshare | Various (ZIP archives, SQL dumps) | Persistent Digital Object Identifiers (DOIs) |
Step-by-Step Guide to Retrieving and Processing 2016 Data
Executing a successful data retrieval workflow requires a systematic approach to searching, downloading, and transforming historical files into usable formats for modern analytical software.
Step 1: Identify the Authoritative Source
Avoid third-party aggregators when high fidelity is required. Trace statistics or raw logs back to the original publishing agency, academic institution, or corporate registry. Use persistent identifiers like DOIs or official archive URLs.
Step 2: Handle Legacy File Formats
Datasets from 2016 may utilize compression algorithms or software versions that are obsolete on modern operating systems.
- Prepare environments capable of handling legacy character encodings (such as transitioning older UTF-8 variants or ISO-8859-1 formats).
- Use modern scripting languages (Python or R) with robust parsing libraries to handle malformed CSV rows or non-standard delimiters common in mid-2010s web scrapes.
Step 3: Perform Data Cleaning and Normalization
Once the raw files are successfully ingested, run standard validation checks:
- Inspect date and timestamp fields to ensure consistent formatting across disparate sources.
- Identify and document missing values, which were often represented inconsistently in 2016-era spreadsheets (e.g., using
N/A,-999, or blank spaces interchangeably).
Frequently Asked Questions
Where can I find official economic data published in 2016?
Official economic data is hosted in the historical archives of institutions like the World Bank, the OECD, and national central banks. These platforms maintain dedicated time-series databases that preserve exact figures published during that calendar year without subsequent retroactive adjustments unless explicitly noted in the metadata.
How do I open legacy geospatial files from 2016?
Geospatial data from 2016 often utilizes formats such as older Shapefiles or NetCDF-3. Modern Geographic Information System (GIS) software like QGIS or geospatial libraries in Python (such as geopandas and xarray) can read these formats, though coordinate reference system (CRS) definitions may require manual updates to align with contemporary standards.
Are 2016 datasets subject to modern privacy regulations like GDPR?
Yes. If a dataset from 2016 contains personally identifiable information (PII) originating from or concerning individuals within jurisdictions governed by regulations like the General Data Protection Regulation (GDPR) or the California Consumer Privacy Act (CCPA), its storage, processing, and access remain subject to those legal frameworks regardless of the year the data was collected.
What should I do if a 2016 data link is broken?
If an official URL from a 2016 publication is inactive, use web archiving services such as the Internet Archive's Wayback Machine to locate cached copies or mirrors of the original repository. Additionally, check if the agency migrated its historical records to a new domain structure.
Conclusion and Recommended Next Actions
Accessing and utilizing 2016 data successfully requires careful attention to file provenance, format compatibility, and metadata validation. Begin your workflow by identifying the exact issuing authority, verify file integrity using checksums where available, and utilize modern parsing tools to clean legacy anomalies before analysis.